Originally published on Ashdown Systems in September 2026, and revised for this blog. Read the original.
If your AWS or Azure bill has started arriving with a slight sense of dread, you’re not alone. It’s one of the most common situations I come across in growing, technology-led businesses: spend has crept up gradually, nobody is quite sure why, and the instinct is to assume the answer is to “use less cloud”. It usually isn’t.
Cloud cost problems are rarely about usage being too high. They’re almost always about an architecture that was never designed with cost in mind, because early on it didn’t need to be. The good news is that this is one of the more fixable problems a scaling business will face, as long as you solve the right problem.
Why cloud costs spiral
Cloud pricing rewards planning and punishes improvisation. That isn’t a criticism of AWS, Azure or GCP; it’s simply the nature of pay-as-you-go infrastructure. The same few patterns turn up again and again:
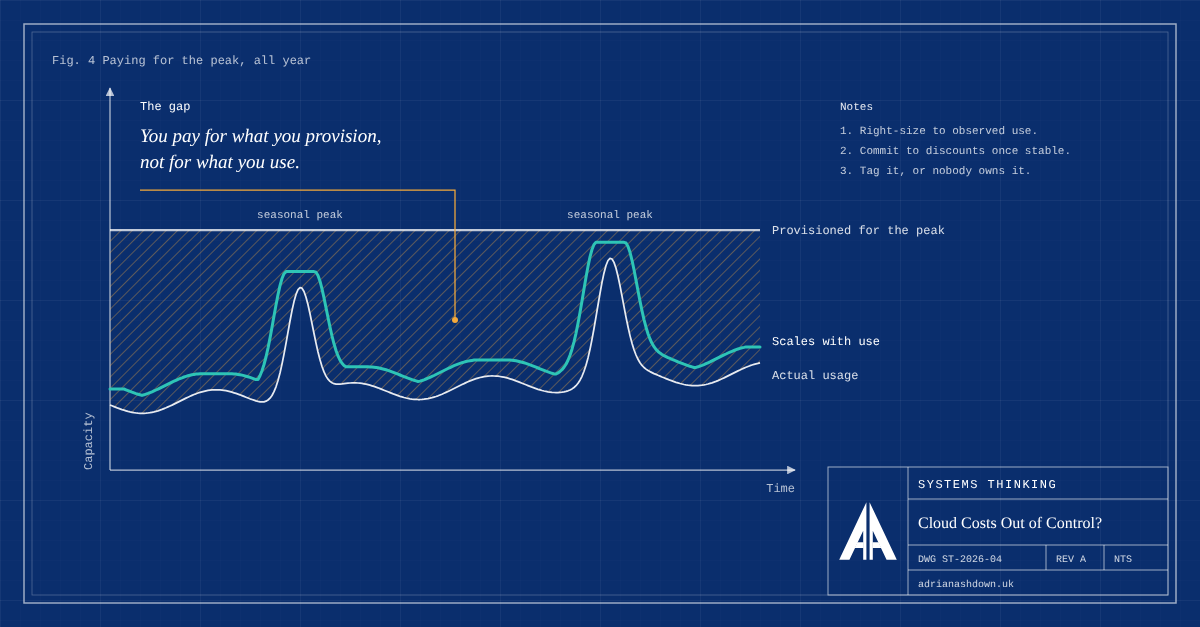
- Over-provisioning “just in case”. Resources sized for a traffic spike that happens twice a year, running at that size for the other 363 days.
- Orphaned resources. Test environments, old databases and unused storage spun up for a project that finished months ago and never switched off.
- No visibility into what drives spend. Without tagging and cost allocation, nobody can say which feature, team or customer accounts for which part of the bill, so nobody can prioritise fixing it.
- Designs that made sense at a smaller scale. A choice that was cheap and simple at low volume can become the biggest line on the bill once usage grows tenfold, without anyone noticing the shift.
- Defaults left untouched. Many services default to convenient rather than cost-efficient, and nobody revisits those settings once the system is live and working.
None of these are exotic. They’re the predictable result of infrastructure decisions made under time pressure by a team focused, rightly at the time, on shipping rather than on the invoice.
Why “just cut costs” is the wrong frame
The instinctive response to a high bill is to go looking for things to switch off. That helps at the margins, but it treats the symptom rather than the cause. It risks cutting something that turns out to matter, or missing the structural issue that will regenerate the same costs within six months.
I find it more useful to start from a different question. Not “what can we cut?” but “does the architecture match how the system is actually used?” That reframing tends to surface bigger, more durable savings than a line-by-line hunt for things to turn off.
Where the real savings usually are
In my experience, the biggest wins fall into a small number of areas:
Right-sizing, done properly. Not just picking a smaller instance, but matching compute and storage tiers to real, observed usage rather than the guess made at launch.
Savings plans and reserved capacity, but only once usage is stable. The discounts can be meaningful, but committing before the architecture has settled can lock in inefficiency rather than remove it.
Designing for elasticity. Systems that scale down as well as up, rather than running at peak capacity permanently, can be the largest single saving available, particularly for workloads with predictable quiet periods.
Storage lifecycle management. Data accessed constantly and data accessed once a year shouldn’t sit in the same expensive tier. This is often one of the simplest fixes with an outsized effect.
Visibility and ownership. Tagging and cost allocation so spend is attributed to the team, product or feature responsible. You can’t optimise what you can’t see, and you can’t hold anyone accountable for a bill nobody can attribute.
A discipline, not a one-off clean-up
The other trap is treating cost optimisation as a single project: one big review, fix the obvious waste, move on. That works once. Then the same drift starts again, because the design choices and habits that caused the problem are still there.
The more durable fix is to make cost part of how architecture decisions are made, so that “what will this cost at scale?” is asked during design, not eighteen months later when the bill has become impossible to ignore.
Why it matters commercially
For a technology-led business, infrastructure cost isn’t a back-office line item. It feeds directly into margins, runway and how much room there is to reinvest in the product. A well-architected system usually performs better and costs less, because most cost inefficiency and most technical fragility share a root cause: an architecture that was never given the chance to be deliberate.
Getting a proper architectural view of cloud spend before deciding what to cut tends to save more money, and cause far less disruption, than starting with the axe.